2.0.0-beta.84 - Packages, Domain & Web Functions
beta.84 splits alchemy into one package per provider, so you install @alchemy.run/aws or @alchemy.run/cloudflare
next to alchemy instead of importing alchemy/AWS. Every AWS, GCP and
Cloudflare binding now works from any host, so a Worker can call SQS and a
Lambda can write to R2.
It also adds @alchemy.run/domain, a domain-driven design framework that
runs on Durable Objects, and rebuilt distilled SDKs that
add 5–100× less overhead per call than the official AWS, Cloudflare and GCP
SDKs, in bundles a third smaller than before. On AWS, there are Lambda Web
Functions with canary deploys. On Cloudflare, alchemy dev for Vite
sites now behaves like @cloudflare/vite-plugin, and the runtime bindings
use a lot less CPU.
One package per provider
Section titled “One package per provider”alchemy keeps the engine, the CLI, and the local and in-memory state
stores. Every cloud and vendor now has its own package, and each one brings
its own resources, bindings and state store, such as AWS.state() or
Cloudflare.state()
(#2348,
#2316,
#2313,
#2311,
#2309):
bun add https://pkg.alchemy.run/alchemy/bb18acb https://pkg.alchemy.run/@alchemy.run/cloudflare/bb18acb https://pkg.alchemy.run/@alchemy.run/aws/bb18acbimport * as Alchemy from "alchemy";import * as AWS from "alchemy/AWS";import * as Cloudflare from "alchemy/Cloudflare";import * as Neon from "alchemy/Neon";import * as Drizzle from "alchemy/Drizzle";import * as Postgres from "alchemy/SQL/Postgres";import * as AWS from "@alchemy.run/aws";import * as Cloudflare from "@alchemy.run/cloudflare";import * as Neon from "@alchemy.run/neon";import * as Drizzle from "@alchemy.run/drizzle";import * as Postgres from "@alchemy.run/sql/Postgres";The same goes for gcp, fly, railway, hetzner, prisma,
planetscale, turso, stripe, github, git, acme, axiom,
doppler, infisical, docker, kubernetes, redis and domain.
Each package exports its directories and files, so
@alchemy.run/aws/S3 and @alchemy.run/aws/S3/Bucket both resolve.
A few things moved within packages:
import * as Cloudflare from "@alchemy.run/cloudflare";solver: ACME.Cloudflare.ZoneSolver(zone),solver: Cloudflare.ACME.ZoneSolver(zone),Stripe.Cloudflare.ConsumeEventsLiveStripe.ConsumeEventsLiveGitHub.Cloudflare.RepositoryEventSourceLiveGitHub.RepositoryEventSourceLiveimport { ServerHost } from "alchemy/Server";import { ServerHost } from "alchemy/Runtime/Process";import { LibSQL } from "alchemy/SQL/LibSQL";import { LibSQL } from "@alchemy.run/sql/SQLite";The CLI finds each provider’s auth, state store and alchemy provider
commands once your project depends on its package, through a new
Contributions module
(#2288). Named state
stores come with it:
state: Cloudflare.state({ name: "team-a" }),alchemy state bootstrap --backend cloudflare --name team-aRuntime bundles shrank along the way. A Worker no longer bundles the stack builder or CLI auth code (346 KB → 216 KB, #2240), and a Lambda that imports the Cloudflare barrel drops from 3.26 MB to 0.84 MB (#2267). Thanks Rahul Mishra, who did most of this split!
OAuth can now create Account API Tokens
Section titled “OAuth can now create Account API Tokens”Cloudflare OAuth can now grant Account API Token Provisioning, so alchemy can mint scoped API tokens on your behalf. To add it, re-run the Cloudflare login and pick All Scopes:
alchemy profile edit --reconfigure CloudflareThen turn the scope on under Sensitive scopes on Cloudflare’s consent page. It’s off by default:
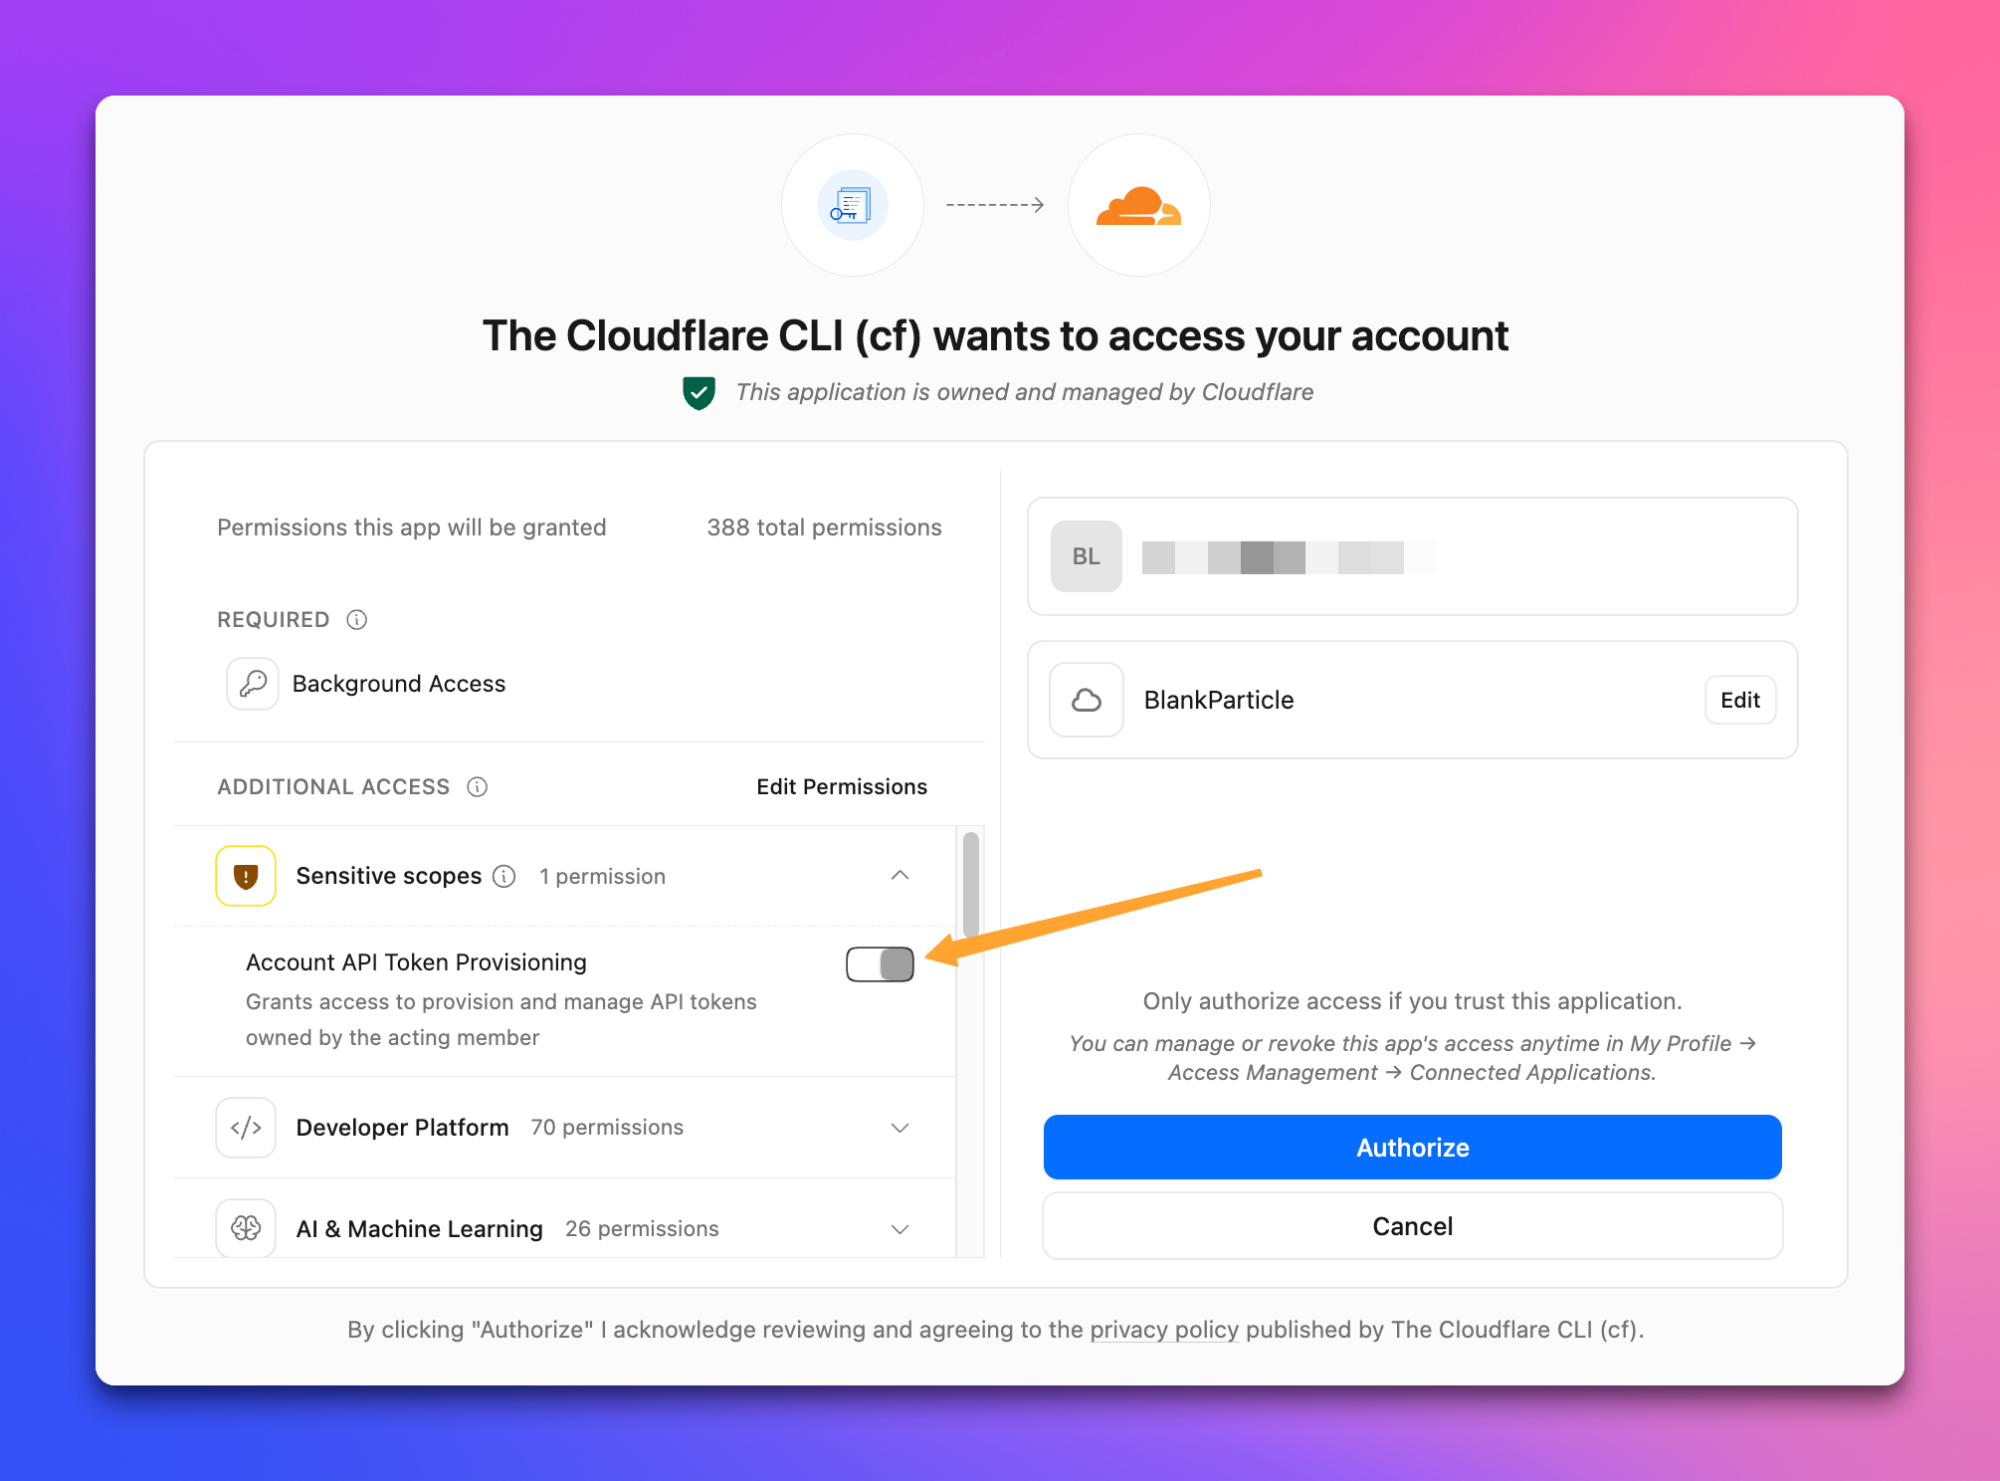
Login now goes through the Cloudflare CLI’s (cf) OAuth client with device
auth, the same flow as cf login
(#2444). Existing
profiles keep refreshing.
Docs: Cloudflare setup.
Every binding works from every cloud
Section titled “Every binding works from every cloud”In beta.83, only the S3, Lambda and DynamoDB bindings worked outside AWS,
no GCP binding worked outside GCP, and Cloudflare’s *Http bindings crashed
on any host that wasn’t a Worker. As part of the package split, every
binding now works on any host: all ~2,850 AWS bindings across 205 services
(#2260), all 192 GCP
bindings across 57 services
(#2347), and every
Cloudflare *Http binding
(#2267).
A Cloudflare Worker sends to SQS with the same binding a Lambda uses. You
provide its *Http layer:
import * as AWS from "@alchemy.run/aws";import * as Cloudflare from "@alchemy.run/cloudflare";import * as Effect from "effect/Effect";import * as HttpServerResponse from "effect/http/HttpServerResponse";
export default class Api extends Cloudflare.Worker<Api>()(  "Api",  { main: import.meta.url },  Effect.gen(function* () {    const queue = yield* AWS.SQS.Queue("Jobs");    const sendMessage = yield* AWS.SQS.SendMessage(queue);    return {      fetch: sendMessage({ MessageBody: "hello" }).pipe(        Effect.map(() => HttpServerResponse.text("queued")),      ),    };  }).pipe(Effect.provide(AWS.SQS.SendMessageHttp)),) {}
On AWS hosts, a binding grants its permissions to the host’s own role. On
any other host, such as a Worker or Cloud Run, Alchemy creates a
least-privilege IAM user and role for it and signs each call with that
role. GCP works the same way with a service account and key. The other
direction works too: a Lambda writes to R2 through
Cloudflare.R2.WriteBucketHttp, which binds a scoped Cloudflare API token.
Hosts that run as a role or service account leave this code out of their
bundles. Thanks Rahul Mishra!
Docs: Bindings.
Domain-driven design with @alchemy.run/domain
Section titled “Domain-driven design with @alchemy.run/domain”@alchemy.run/domain models your backend in your business’s terms
(#2176). Commands ask
for changes, aggregates decide them, and events record what happened.
Views, policies, sagas and projections react to those events. The same
model runs in memory for tests and on Durable Objects in production.
A command declares its target, input, events, rejections and reply:
import * as Domain from "@alchemy.run/domain";
export class MoneyDeposited extends Domain.Event("MoneyDeposited", {  amount: Schema.Int,  balanceAfter: Schema.Int,}) {}
export class DepositMoney extends Domain.Command("DepositMoney", {  target: AccountId,  input: { amount: Schema.Int },  events: [MoneyDeposited],  rejects: [NotOpen],  reply: { balance: Schema.Int },}) {}
The aggregate decides it against its current state:
DepositMoney: (s, cmd) => s._tag !== "Open" ? new NotOpen() : [new MoneyDeposited({ amount: cmd.amount, balanceAfter: s.balance + cmd.amount })],A story tests it in memory: given this history, when this command, then these events.
story( Story.given(account, new AccountOpened({ owner: "sam" })), Story.when(account, new DepositMoney({ amount: 100 })), Story.then(account, new MoneyDeposited({ amount: 100, balanceAfter: 100 })), Story.replied({ balance: 100 }),);On Cloudflare, provide DomainCloudflare.DurableObjects and every
aggregate, view key and policy gets its own Durable Object. Views are
security boundaries, and clients can watch them live over WebSockets. The
package ships an alchemy-domain skill so your coding agent can build a
model with you.
Docs: Domain · Tutorial · Cloudflare Durable Objects.
Smaller, faster distilled SDKs
Section titled “Smaller, faster distilled SDKs”Alchemy’s cloud SDKs come from distilled. This release picks up a rebuilt distilled (distilled#873, #2345) that dedupes schemas, builds them lazily, and replaces Effect Schema with a lighter schema tree. Medians over 98 one-auth, one-call programs:
| Before | After | Change | |
|---|---|---|---|
| Bundle size (gzip) | 57.1 KB | 38.3 KB | −33% |
| Added latency per call (p50) | 19.5 µs | 4.0 µs | −79% |
| Import heap | 2.15 MB | 0.57 MB | −74% |
| First call (cold) | 4.9 ms | 3.3 ms | −34% |
Importing a whole provider is where it shows most. AWS has 438 services, GCP 318 and Cloudflare 129:
| Provider | Import heap | Import time |
|---|---|---|
| AWS | 227 MB → 13.9 MB | 1.61 s → 0.14 s |
| GCP | 111 MB → 9.4 MB | 0.75 s → 0.09 s |
| Cloudflare | 76 MB → 3.2 MB | 0.63 s → 0.05 s |
The packages you install from npm shrink too:
| Package | Download (tgz) | Unpacked |
|---|---|---|
@distilled.cloud/aws |
23.3 MB → 19.3 MB | 211 MB → 143 MB |
@distilled.cloud/gcp |
42.3 MB → 36.1 MB | 345 MB → 262 MB |
@distilled.cloud/cloudflare |
9.5 MB → 5.8 MB | 112 MB → 58 MB |
Faster than the official SDKs
Section titled “Faster than the official SDKs”The same calls through the official SDKs: AWS SDK v3, the Stainless-built
cloudflare package, and @google-cloud/storage. Each official program
imports one client. Each distilled program imports the whole provider and
is still smaller:
| Call | Added latency per call | Bundle (gzip) | Import heap |
|---|---|---|---|
GCP storage.getBuckets |
674 → 6.2 µs | 239 → 40 KB | 5.1 → 0.7 MB |
S3 ListBuckets |
140 → 19 µs | 157 → 61 KB | 4.4 → 1.1 MB |
| EC2 | 97 → 16 µs | 265 → 55 KB | 12.2 → 1.5 MB |
| DynamoDB | 87 → 14 µs | 145 → 54 KB | 3.3 → 1.0 MB |
| Lambda | 79 → 15 µs | 141 → 55 KB | 3.6 → 1.1 MB |
Cloudflare workers.scripts.list |
15.5 → 3.0 µs | 125 → 56 KB | 15.3 → 0.7 MB |
Distilled adds 5–100× less overhead per call, ships bundles 2–6× smaller, and imports with 3–22× less memory. Its first cold call is faster too, except on Cloudflare, where it takes 3.4 ms against the official SDK’s 1.9 ms.
The Cloudflare package now signs R2 presigned URLs
with the standalone @distilled.cloud/aws4signer, so it no longer depends
on the AWS SDK (#2370).
Thanks Michael K!
Plan and apply scale linearly
Section titled “Plan and apply scale linearly”Plan and apply used to do work proportional to the square of the stack’s resource count. Apply rebuilt every resource’s outputs once per resource, and plan scanned every node to find each node’s dependents. Both are now linear (#2419):
| Stack shape | Resources | Before | After |
|---|---|---|---|
| Independent | 4,000 | 3.4 s | 1.7 s |
| Independent | 8,000 | 9.5 s | 3.8 s |
| 20 dependencies each | 1,000 | 1.2 s | 1.1 s |
| 20 dependencies each | 2,000 | 3.3 s | 2.1 s |
Timings are engine overhead only, measured with no-op providers. Thanks gpu004 for profiling it!
Foldkit SSR and prerendering
Section titled “Foldkit SSR and prerendering”Foldkit apps can now render on the server and
prerender pages, on every website provider
(#1313). Turn on
ssr.build in the Foldkit Vite plugin:
export default defineConfig({ plugins: [ foldkit({ ssr: { serverEntry: "/src/entry.server.ts", clientEntry: "/src/entry.ts", build: { prerender: true }, }, }), ],});Alchemy deploys the server Foldkit generates and serves prerendered pages as static files. On Cloudflare, Fly, Hetzner, Railway, Neon, Prisma and GCP, the build decides whether the site is an SPA, static, SSR or a hybrid:
const site = yield* Cloudflare.Website.Foldkit("Web");On AWS, you choose between a server and a static site:
const app = yield* AWS.Website.Foldkit("Web", { output: "server" });const docs = yield* AWS.Website.Foldkit("Docs", { output: "static", errorPage: "404.html" });Foldkit pairs with @alchemy.run/domain for the
front end of a domain model. Thanks
Filip Falcon!
Docs: Foldkit on Cloudflare · Foldkit on AWS.
Lambda Web Functions
Section titled “Lambda Web Functions”AWS.Lambda.WebFunction runs your HTTP server on Lambda Web
Functions
(#2243). Each
environment serves up to 128 requests at once, responses stream, and every
function gets an HTTPS endpoint. An Effect Web Function returns fetch,
and existing bindings work unchanged:
export default class Api extends AWS.Lambda.WebFunction<Api>()( "Api", { main: import.meta.url, authType: "ApplicationManaged" }, Effect.gen(function* () { const bucket = yield* AWS.S3.Bucket("Uploads"); const putObject = yield* AWS.S3.PutObject(bucket); return { fetch: Effect.gen(function* () { yield* putObject({ Key: "hello.txt", Body: "Hello!" }); return HttpServerResponse.text("Saved"); }).pipe(Effect.orDie), }; }).pipe(Effect.provide(AWS.S3.PutObjectHttp)),) {}Or bring your own server (Hono, Express, node:http). It listens on
AWS_LAMBDA_HTTP_ENDPOINT:
yield* AWS.Lambda.WebFunction("Api", { main: "./src/server.ts", authType: "ApplicationManaged", regions: ["us-east-1", "eu-west-1"], // one global domain});canary sends a share of traffic to each new deploy
(#2280). Edit the
weight to promote or roll back:
canary: { weight: 10 }, // the new revision gets 10%, the previous one 90%Every server-rendered AWS.Website (Nuxt, SvelteKit, Astro, React Router,
SolidStart, TanStack Start, Waku, Octane, Vinext) now runs on a Web
Function by default
(#2282). Next.js runs
as its own standalone server with an S3 cache, without OpenNext, SQS or
DynamoDB (#2300).
Existing sites roll forward on the next deploy.
Docs: Web Functions · Next.js.
Effect workflows on every engine
Section titled “Effect workflows on every engine”alchemy/Workflows runs effect/workflow workflows on Durable Objects,
Cloudflare Workflows, and Lambda durable functions
(#2252,
#2268,
#2390).
Workflows.layer implements a workflow. Pass it an Effect that resolves
bindings, here an R2 bucket, and return the handler that uses them:
import * as Cloudflare from "@alchemy.run/cloudflare";import * as Workflows from "alchemy/Workflows";import * as Effect from "effect/Effect";import * as Schema from "effect/Schema";import { Activity, DurableClock, Workflow } from "effect/workflow";
export const Profiles = Cloudflare.R2.Bucket("Profiles");
export const Onboard = Workflow.make("Onboard", {  payload: { userId: Schema.String },  success: Schema.String,  idempotencyKey: ({ userId }) => userId,});
export const OnboardLive = Workflows.layer(  Onboard,  Effect.gen(function* () {    const profiles = yield* Cloudflare.R2.WriteBucket(Profiles);    return Effect.fn(function* ({ userId }) {      yield* Activity.make({        name: "create-profile",        execute: profiles          .put(`${userId}.json`, JSON.stringify({ userId, plan: "trial" }))          .pipe(Effect.orDie),      });      // the run suspends for a week and costs nothing while it waits      yield* DurableClock.sleep({ name: "trial", duration: "7 days" });      yield* Activity.make({        name: "end-trial",        execute: profiles          .put(`${userId}.json`, JSON.stringify({ userId, plan: "free" }))          .pipe(Effect.orDie),      });      return `onboarded ${userId}`;    });  }),);
The Worker starts runs with Workflows.RunWorkflow and reads them back.
Give it the implementation, the R2 binding and an engine, here Durable
Objects:
import * as Cloudflare from "@alchemy.run/cloudflare";import * as Workflows from "alchemy/Workflows";import * as Effect from "effect/Effect";import { HttpServerRequest } from "effect/http/HttpServerRequest";import * as HttpServerResponse from "effect/http/HttpServerResponse";import * as Layer from "effect/Layer";import { Onboard, OnboardLive } from "./Onboard.ts";
export default class Api extends Cloudflare.Worker<Api>()(  "Api",  { main: import.meta.url },  Effect.gen(function* () {    const onboard = yield* Workflows.RunWorkflow(Onboard);    return {      fetch: Effect.gen(function* () {        const request = yield* HttpServerRequest;        const url = new URL(request.url, "http://localhost");        if (request.method === "POST") {          const userId = url.searchParams.get("user")!;          const run = yield* onboard.start({ userId });          return HttpServerResponse.text(run.executionId);        }        const runId = url.searchParams.get("run")!;        // NotStarted | Running | Completed | Failed | Interrupted | Died        const status = yield* onboard.get(runId).status;        return HttpServerResponse.text(status._tag);      }).pipe(Effect.orDie),    };  }).pipe(    Effect.provide(      OnboardLive.pipe(        Layer.provide(Cloudflare.R2.WriteBucketBinding),        Layer.provideMerge(Cloudflare.Workflows.DurableObjectEngine),      ),    ),  ),) {}
Swap DurableObjectEngine for Cloudflare.Workflows.NativeEngine to run
it on Cloudflare Workflows instead. On AWS, host workflows in an
AWS.Lambda.WorkflowFunction and start them from other functions with
AWS.Lambda.DurableFunctionEngine.
Docs: Cloudflare · AWS.
Vite dev that matches @cloudflare/vite-plugin
Section titled “Vite dev that matches @cloudflare/vite-plugin”A Website.Vite Worker now behaves in alchemy dev as it does deployed,
and as it does under @cloudflare/vite-plugin
(#2367,
#2365,
#2144). Durable
Objects from other Workers, Workflows, Containers, WebSockets, ctx.access,
Node.js polyfills, HTTPS dev servers and Wrangler’s /cdn-cgi/local/*
endpoints all work in dev. Asset routing follows your htmlHandling,
notFoundHandling and runWorkerFirst:
yield* Cloudflare.Website.Vite("App", { main: "./api/index.ts", assets: { notFoundHandling: "single-page-application", runWorkerFirst: ["/api/*"] },});// dev before: /api/some-file.txt → the file on disk// dev now: /api/some-file.txt → the Worker, as deployedA Vite config that keeps cloudflare() from @cloudflare/vite-plugin now
runs, so RedwoodSDK, Flue and the Agents SDK build as documented. Tests
run the official plugin next to Alchemy’s on the same projects and compare
config, build output and runtime behavior. The full list is in
PARITY.md.
The dev server also refuses .env, .dev.vars and .alchemy/, and no
longer forwards a request like //127.0.0.1:47667/x to another local port
(#2381). Thanks
Arman Charan!
Faster Cloudflare runtime
Section titled “Faster Cloudflare runtime”Dan van der Merwe measured the runtime bindings on deployed Workers and Durable Objects and cut their CPU time:
| Workload | Mean CPU before → after |
|---|---|
Copy a 16 MiB R2 object with get + put (#2276) |
630 → 3.8 ms |
| Prepare five 1 MiB Workers AI images (#2274) | 270 → 10.6 ms |
| 1,000 workflow result round trips (#2271) | 358 → 32 ms |
| 2 MiB through the RPC codec (#2272) | 85 → 20 ms |
| Pack 500 queue messages (#2275) | 235 → 92 ms |
| Drain 1,000 Durable Object scheduled events (#2277) | 33 → 8.4 ms |
| 2,000 env reads in a Durable Object (#2279) | 29 → 4.9 ms |
SQL cursors allocate only what you use (#2281). RPC streams whose values arrive after the method returns now deliver every value (#2273), and durable callbacks that keep failing now back off and park after eight attempts instead of waking forever (#1908).
RDS migrations everywhere
Section titled “RDS migrations everywhere”migrations now works on every PostgreSQL, MySQL and MariaDB
DBInstance, standalone or Aurora
(#2125,
#2289). Aurora runs
them over the Data API. A public database connects directly, and a
private one runs them from a Lambda in the VPC:
const runner = yield* AWS.RDS.MigrationRunner("MigrationRunner", {  subnetIds: network.privateSubnetIds,  securityGroupIds: [runnerSecurityGroup.groupId],});
const db = yield* AWS.RDS.DBInstance("Db", {  engine: "mysql",  // ...  migrations: "./migrations",  migrationsTransport: runner,});
Thanks gegi!
Docs: RDS · Drizzle on Aurora.
GCP state store
Section titled “GCP state store”GCP.state() keeps deploy state in a Cloud Storage bucket in your project
(#2379):
export default Alchemy.Stack( "MyApp", { providers: GCP.providers(), state: GCP.state() }, program,);alchemy state bootstrap --backend gcpAWS.state() now locks each stack and stage too, so two concurrent
deploys of one stage can no longer mix their state
(#2145). Thanks
Arman Charan! The GCP docs are rebuilt
around a five-part tutorial
(#2374).
Fly remote builds
Section titled “Fly remote builds”Fly.Service images now build on Fly’s remote builders, the same ones
fly deploy uses (#2472).
Only your bundled app leaves your machine: the builder pulls the base image,
builds, and pushes to registry.fly.io right next to it. Deploys no longer
upload the whole ~86 MB node:26-slim image for every Service, which made
them slow on home and CI connections. Nothing to change in your stack:
// builds on a Fly remote builderyield* Fly.Service("Api", { main: import.meta.url });
// build and push with your local Docker engine insteadyield* Fly.Service("Api", { main: import.meta.url, build: { remote: false } });
Docs: Fly services.
Also in this release
Section titled “Also in this release”GCP.IAM.ServiceAccountandServiceAccountKeyresources (#2347).Cloudflare.Hyperdrive.lookup(#1345) binds an existing Hyperdrive configuration without managing it. Thanks Franz Rebaza!ctx.propsandctx.exportsin Effect Workers and Durable Objects (#2251), and hibernationtagsonCloudflare.upgrade()(#2265). Thanks gegi!- Container placement
jurisdictionandregionsare typed (#2253), local containers can mount FUSE filesystems (#2362), and detached or adopted container applications redeploy cleanly (#2378, #2283). Containers built from inline Dockerfile content deploy (#2341), andmonitor()fails with the same typed placement errors asstart()(#2340). Thanks Jakub Sieczczyński, Jonathan Beckman, Yannic Charlon and Drew Powers! localUploadsonCloudflare.R2.Bucket(#2424).- Cloudflare fixes: a failed ruleset read no longer wipes a zone’s
other rules when a Worker sets
domain.redirectsorversion.affinity(#2339),WorkerEntrypointtargets a cross-stackWorker.ref(#2414), a rotatedMtlsCertificateuploads the new PEM (#2428), and a Hyperdrive config replaces when its CA pin is dropped (#2429). Thanks Drew Powers! - Cloudflare website builds receive
env, soNEXT_PUBLIC_*,VITE_*and similar values reach the client bundle (#2238), and a full Worker deploy returns itsversionIdanddeploymentId(#2241). Thanks Kevin! - Local dev fixes:
/.well-known/assets serve (#2212), large D1 migrations andimportFilesapply (#2380, #2258),publicDirfiles serve throughASSETS(#2290),StaticSitetakesdev.port(#2331), tail consumers receive events and each Worker gets its own Cache store (#2383), port probes stay on loopback (#2237), and early responses no longer reset the connection (#2242). Thanks birbprophet, Altay, Kevin and Matthew Ruiters! - Cloudflare deploys on Node 26 use HTTP/1.1 for API calls, avoiding stream resets (#2155), and Durable Object RPC retries through deploy propagation (#2294).
metadataOptionsonAWS.EC2.InstanceandLaunchTemplate(#2426),RedacteduserDataonInstance(#2421), and a VPC whose create was interrupted is recovered instead of leaked (#2416).AWS.RDS.Auroraaccepts Outputs forkmsKeyIdandmigrations(#2364). Thanks gegi!- AWS fixes:
Lambda.KafkaEventSourcegrants the EC2 permissions MSK mappings need (#2401),EMRContainers.VirtualClusterwaits for a new EKS cluster’s connection (#2412), andDataZone.EnvironmentBlueprintConfigurationremoves the Lake Formation admins DataZone added (#2411). - ~200 more AWS resources run on floci in
alchemy dev(#1803). - AgentCore Runtime V2 with
platformVersion(#2301), ECS dev watcher keeps the recorded task definition (#2091). Thanks Henry Marks and TBIQ007! - Railway ephemeral environments (#2117) and a 768 MiB Prisma Compute upload cap (#2257). Thanks Mikkel and Aman Varshney!
GitHub.consumeRepositoryEventsgenerates a webhook secret when you omit one, so every delivery’s signature is checked (#1932).GitHub.RulesettakesallowedMergeMethodsandrequireExtraApprovalForUnattributedChanges(#2397) and adopts an existing ruleset by name (#2129), andGitHub.BranchProtectiondeploys withrequiredStatusChecks.checks(#2076). Thanks Jason Kuhrt, Patt O’Brien and Arman Charan!- Core fixes: declaring a logical id already used by another type fails
with
DuplicateLogicalIdError(#2063),afterAll(destroy(Stack))no longer hangs under Vitest (#2142), aDocker.Contextmissing from a fresh CI runner is re-created (#2187), log redaction no longer leaks the tail of a secret that extends a shorter one (#2418), tarballs keep long non-ASCII file names intact (#2420), andalchemy/Statetype-checks underexactOptionalPropertyTypes(#2413). Thanks Arman Charan and Patt O’Brien! - The CLI runs on Node 22.22.3+ again (#2403), and
alchemy profile refresh --providermatches case-insensitively (#2410). Thanks Rahul Mishra! alchemy profileno longer crashes withCannot find package 'react'(#2295), and Workers bundle less core code (#2240). Thanks birbprophet and Juliaan!